Summary and contents
Summary
- Thinking time did not correlate with accuracy. When transcribing tables, the setting that thinks longest gave both the worst result (32 errors, about 33 minutes for two tables) and the best one. In one run it repeated the same passage 16 times while thinking.
- Thinking raised confidence, not correctness. On a question that needs a rule applied, light thinking stated its conclusion firmly all three times, and all three times it misread the rule. No thinking and the strongest thinking did not decide. This question depends on interpretation and the document alone does not settle it, so not deciding is the good answer (recheck on 4 November).
- Instructions meant for any document did not improve accuracy. On 4 November we confirmed the same tendencies on Strata 0.2.10 and also tried another document (a home-appliance manual). All runs, including those before Strata, are in one list.
- The wrong fare answer was not the model's fault. "Which column is which station" was lost when the table was turned into search text. With that fixed, the model answers correctly without thinking in 18–45 s (before: 9–21 minutes with thinking, and one wrong answer in three).
- Both models read the tables about equally well. The differences came from one model declaring its own good readings "unreadable" (so the pipeline dropped them) and from an output limit that was too small.
- A much larger answer model did not answer more questions right. Of 14 questions, the current model answered 13 right and decisively, the larger one 10. The larger model never stated a wrong answer, but left the answer open when the evidence lacked the question's own words, and took about 3.6 times as long on this PC.
- Changing only the PC changed the answer to the interpretive question. On 5 November we ran the same tests again on the i7 PC, raised to 125 GiB of RAM. Table reading and the 13 factual questions came out almost the same, and answers were 10–30% faster. On the correspondence question, though, Qwen and llm-jp (the answer model before Strata) said "cannot buy" firmly all 3 times, with the same weights at temperature 0. DeepSeek never said it firmly in 16 runs on two PCs.
Overall assessment
Taking all the tests on this page together (25 October to 5 November 2026): this RAG is practical for looking up facts, and the best answer model is Qwen (Qwen3.8-Flash-Next) on Strata without thinking. It cannot yet be relied on for questions that need a rule applied or interpreted.
| Area | Rating | Basis |
|---|---|---|
| Looking up facts (amounts, numbers, whether something is allowed as written) | ◎ | Qwen at strength 0 answered all 13 questions on this source right and decisively on every version, and all 14 on a home-appliance manual that was not looked at while building the system. No answer stated a wrong conclusion. |
| Table reading (building the index) | ○ | Ordinary tables are about equal for every model (match 0.85–0.90). On staircase fare tables Strata's Qwen was best with 6–8 errors; before Strata there were 214 errors or an empty reading. |
| Applying and interpreting rules | △ | On the correspondence-school question the answer varied between runs with the same settings, and thinking made a firm "cannot buy" more likely (5 of 6 runs). Adding instructions meant for any document did not fix it. On another PC on 5 November, Qwen said it firmly all 3 times even at strength 0. |
| Speed | ○ | 26 s a question (Qwen, 0.2.10; 19 s on the i7 PC on 5 November), most of it the search on the CPU (24–28 s). |
| Independence from the document | ○ | The prompts for answering, planning the search and reading tables contain no words specific to this source. The staircase rewrite and prompt A's example still carry the idea of a fare table. |
Answer models
| Model | 13 questions: right and decisive | Left open or no answer | Mean time | Character |
|---|---|---|---|---|
| Qwen3.8-Flash-Next (Strata) | 13 | 0 | 26 s | Fast, accurate and decisive; wavers only on the interpretive question. |
| DeepSeek-V4.1-Flash (Strata) | 10 | 3 | 52 s | Never states anything false, but hedges when the evidence does not name the thing word for word. |
| llm-jp-4.1-8b-thinking (before Strata) | 11 | 2 | 39 s | Close in accuracy; its reasoning can run into the answer length limit and get cut off. |
What Strata changed
- The big change was in building the index. Staircase fare tables can now be read, and that is why the fare questions (Kita-Senju → Hon-Atsugi, 810 yen, and others) can be answered.
- The difference in answer accuracy was small: 13 questions against 11 for the answer model used before Strata.
Weaknesses and open issues
- Questions that depend on interpretation. The system does not reliably answer "the document alone does not decide; it depends on X". Adding instructions to the prompt did not fix it.
- Thinking hurts. In both answering and table reading it made firm wrong statements more likely and took much longer. No thinking is the right setting.
- Run-to-run variation. Even at temperature 0, answers can change with the day or the version. Most results are one run per question. On 5 November, changing only the PC changed the answers to the correspondence question (details).
- A small evaluation. Two documents, about 30 questions. The manual was already answered perfectly, so it cannot tell settings apart.
- Pipeline limits. A reasoning model can hit the answer output cap (1,024 tokens). The search on the CPU is slow, and the index still holds a chunk with a different amount (860 yen).
Next steps
- In production, answer with Qwen without thinking and keep the staircase-table rewrite.
- Mark interpretive questions in the question sets and score them by what the answer shows and what it leaves undecided.
- To make the evaluation meaningful, add documents and harder questions: conditions, exclusions and conflicting rules.
- For speed, move the embedding search, the largest remaining share of the time, to the GPU or a lighter model.
Findings
Longer thinking, no better accuracy
Raising the thinking strength made runs up to more than ten times longer, but errors did not go down. Repeating the same setting gave widely different results.
The answer is set early
In long thinking runs the answer was fixed within roughly the first tenth; the rest repeated the same checks. A misreading at the start was not corrected by thinking more.
Confident is not correct
On a question that needs a rule applied, light thinking gave the same wrong answer with confidence all three times. One run without thinking pointed out the exclusion clause correctly. On plain look-up questions, thinking made no difference.
The cause was the table's text form
With staircase fare tables stored as "origin → destination: fare" lines, the model answered correctly without thinking. Before, it took 9–21 minutes with thinking.
What decided RAG accuracy
Light thinking made repeated runs collapse less often, but it could also turn a misread rule into a confident answer. Strong thinking took far longer, fell into repeating itself, or would not commit to a conclusion.
If the search text no longer says what each column means, the model can only guess, and whether it guesses right is down to luck.
Source and setup
- Source: a railway company's passenger tariff, as a 98-page PDF. Besides the articles it holds many station-to-station tables, such as distance and limited-express fare tables.
- RAG: our own ingestion pipeline (tables read from the page image, checked and approved by a person, then registered for search) and its answering step (split the question, search for evidence, answer citing it), used as they are.
- Models:
- Qwen3.8-Flash-Next ("Qwen" below; Unsloth UD-Q4_K_XL), served by Strata; the main model on this page.
- gemma-4-12b-it ("gemma"; Q4_K_M, llama.cpp), the table reader used before Strata; for comparison.
- DeepSeek-V4.1-Flash ("DeepSeek"; 2.00 bpw), a much larger model also served by Strata.
- llm-jp-4.1-8b-thinking ("llm-jp"; Q4_K_M, llama.cpp), the answer model used before Strata.
- Earlier vision model: Qwen2.5-VL-7B-Instruct (Q4_K_M), which read whole pages before Strata.
- Thinking strength: Qwen lets you choose how much it thinks before answering. On this page, no thinking is "strength 0", and the levels go up to "strength 3" for the most thinking.
- Prompts: besides the baseline prompt, two other instructions ("prompt A", "prompt B") were tried for table reading. Their wording is not published.
- Scoring: fare tables were checked against fares copied by hand from the printed image, station by station and tier by tier; each wrong number counts as one error.
Table reading: two models
Ten approved tables (forms, distance, fare and dangerous-goods tables) were read by both models, without thinking.
| Table | Qwen | gemma |
|---|---|---|
| Distance and fare tables (3) | 0.99–1.00 | 0.99–1.00 |
| Fares to a connecting JR line | 1.00 | 0.97 |
| Limited-express fares (upper) | 0.97 | 0.98 |
| Limited-express fares (lower) | 0.97 | 0.89 * |
| Time per table (mean) | 106 s | 52 s |
- Accuracy was about the same. The gap came from two tables that gemma read well but flagged as unreadable.
- Qwen was about twice as slow, because its image encoder runs on the CPU.
- We also found a pipeline problem. For a table with no text layer (the fare tables are printed as images), the output limit came to 256 tokens and both models were cut off. That, not the models, is why those fare tables had come out empty.
See it: reading the fare tables
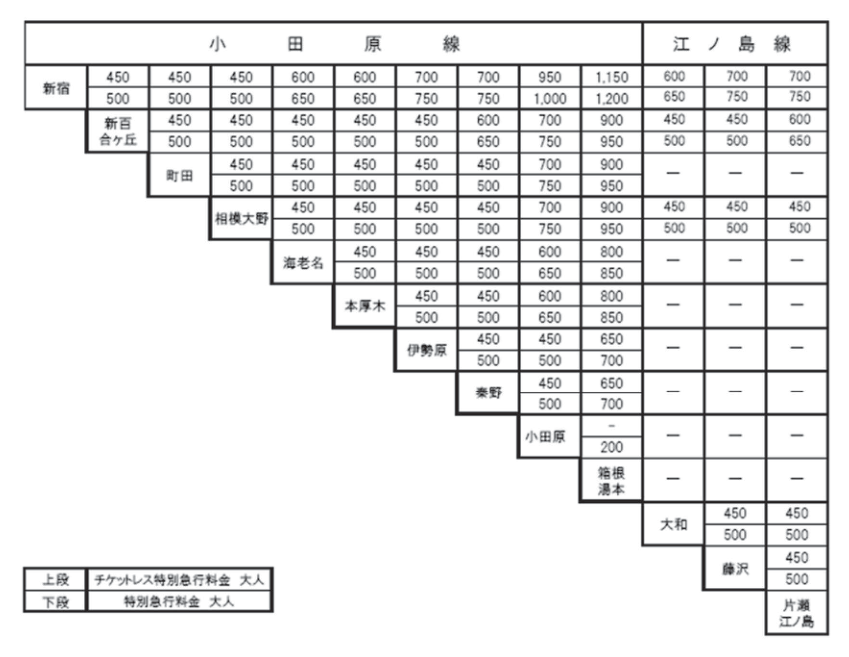
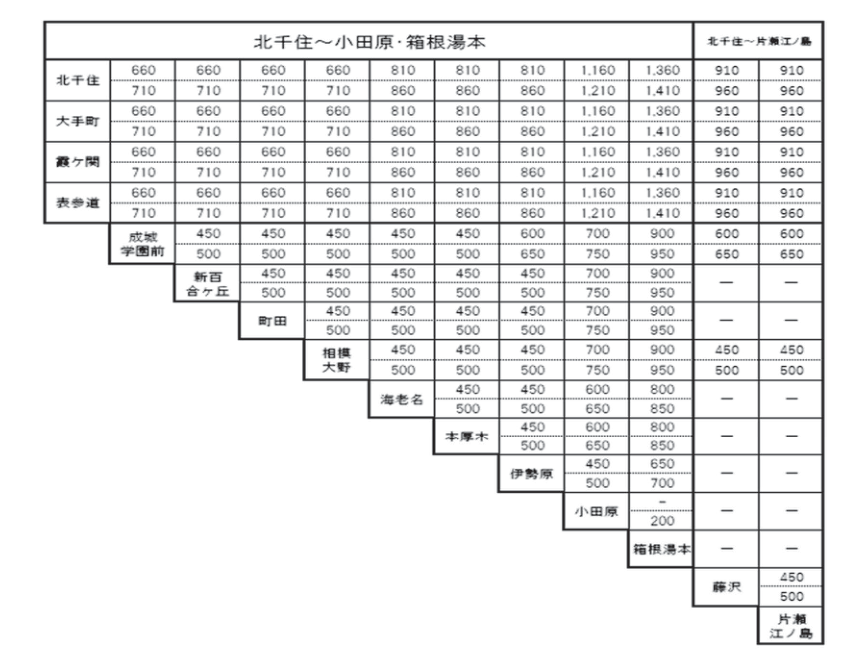
For the two limited-express fare tables where the gap was largest: the printed table, and each model's reading exactly as written. A cell differs from the fares copied by hand from the image. A fare left out cannot be marked in a cell, so it is counted as "missing" next to the error count. Rows left entirely empty are not shown.
Limited-express fares (upper): from Shinjuku
| 小田原線 | 江ノ島線 | |||||||||||||
| 新宿 | 450 | 450 | 450 | 600 | 600 | 700 | 700 | 950 | 1,150 | 600 | 700 | 700 | ||
| 500 | 500 | 500 | 650 | 650 | 750 | 750 | 1,000 | 1,200 | 650 | 750 | 750 | |||
| 新百合ヶ丘 | 450 | 450 | 450 | 450 | 450 | 600 | 700 | 900 | 450 | 450 | 600 | |||
| 500 | 500 | 500 | 500 | 500 | 650 | 750 | 950 | 500 | 500 | 650 | ||||
| 町田 | 450 | 450 | 450 | 450 | 450 | 700 | 900 | |||||||
| 500 | 500 | 500 | 500 | 500 | 750 | 950 | ||||||||
| 相模大野 | 450 | 450 | 450 | 450 | 700 | 900 | 450 | 450 | 450 | |||||
| 500 | 500 | 500 | 500 | 750 | 950 | 500 | 500 | 500 | ||||||
| 海老名 | 450 | 450 | 450 | 600 | 800 | |||||||||
| 500 | 500 | 500 | 650 | 850 | ||||||||||
| 本厚木 | 450 | 450 | 600 | 800 | ||||||||||
| 500 | 500 | 650 | 850 | |||||||||||
| 伊勢原 | 450 | 450 | 650 | |||||||||||
| 500 | 500 | 700 | ||||||||||||
| 秦野 | 450 | 650 | ||||||||||||
| 500 | 700 | |||||||||||||
| 小田原 | ||||||||||||||
| 200 | ||||||||||||||
| 箱根 | ||||||||||||||
| 湯本 | ||||||||||||||
| 大和 | 450 | 450 | ||||||||||||
| 500 | 500 | |||||||||||||
| 藤沢 | 450 | |||||||||||||
| 500 | ||||||||||||||
| 片瀬 | ||||||||||||||
| 江ノ島 | ||||||||||||||
| 上段 | チケットレス特別急行料金 大人 | |||||||||||||
| 下段 | 特別急行料金 大人 |
| 新宿 | 450 | 450 | 450 | 600 | 600 | 700 | 700 | 950 | 1,150 | 600 | 700 | 700 |
| 500 | 500 | 650 | 650 | 750 | 750 | 1,000 | 1,200 | 650 | 750 | 750 | ||
| 新百合ヶ丘 | 450 | 450 | 450 | 450 | 450 | 600 | 700 | 900 | 450 | 450 | 600 | |
| 500 | 500 | 500 | 500 | 500 | 650 | 750 | 950 | 500 | 500 | 650 | ||
| 町田 | 450 | 450 | 450 | 450 | 450 | 700 | 900 | — | — | — | ||
| 500 | 500 | 500 | 500 | 500 | 750 | 950 | — | — | — | |||
| 相模大野 | 450 | 450 | 450 | 450 | 700 | 900 | 450 | 450 | 450 | |||
| 500 | 500 | 500 | 750 | 950 | 500 | 500 | 500 | |||||
| 海老名 | 450 | 450 | 450 | 600 | 800 | — | — | — | ||||
| 500 | 500 | 500 | 650 | 850 | — | — | — | |||||
| 本厚木 | 450 | 450 | 600 | 800 | — | — | — | |||||
| 500 | 500 | 650 | 850 | — | — | — | ||||||
| 伊勢原 | 450 | 450 | 650 | — | — | — | ||||||
| 500 | 500 | 700 | — | — | — | |||||||
| 秦野 | 450 | 650 | — | — | — | |||||||
| 500 | 700 | — | — | — | ||||||||
| 小田原 | - | — | — | — | ||||||||
| 200 | — | — | — | |||||||||
| 箱根湯本 | — | — | — | |||||||||
| 大和 | 450 | 450 | ||||||||||
| 500 | 500 | |||||||||||
| 藤沢 | 450 | |||||||||||
| 500 | ||||||||||||
| 片瀬江ノ島 |
| 新宿 | 450 | 450 | 450 | 600 | 600 | 700 | 700 | 950 | 1,150 | 600 | 700 | 700 |
| 新宿 | 500 | 500 | 650 | 650 | 750 | 750 | 1,000 | 1,200 | 650 | 750 | 750 | |
| 新百合ヶ丘 | 450 | 450 | 450 | 450 | 600 | 700 | 700 | 900 | 450 | 450 | 600 | |
| 新百合ヶ丘 | 500 | 500 | 500 | 500 | 650 | 750 | 950 | 500 | 500 | 650 | ||
| 町田 | 450 | 450 | 450 | 450 | 600 | 700 | 900 | 450 | 450 | 600 | ||
| 町田 | 500 | 500 | 500 | 500 | 650 | 750 | 950 | 500 | 500 | 650 | ||
| 相模大野 | 450 | 450 | 450 | 450 | 700 | 900 | 450 | 450 | 450 | |||
| 相模大野 | 500 | 500 | 500 | 500 | 750 | 950 | 500 | 500 | 500 | |||
| 海老名 | 450 | 450 | 450 | 600 | 800 | − | − | − | ||||
| 海老名 | 500 | 500 | 500 | 650 | 850 | − | − | − | ||||
| 本厚木 | 450 | 450 | 600 | 800 | − | − | − | |||||
| 本厚木 | 500 | 500 | 650 | 850 | − | − | − | |||||
| 伊勢原 | 450 | 450 | 650 | − | − | − | ||||||
| 伊勢原 | 500 | 500 | 700 | − | − | − | ||||||
| 秦野 | 450 | 650 | − | − | − | |||||||
| 秦野 | 500 | 700 | − | − | − | |||||||
| 小田原 | − | − | − | − | ||||||||
| 小田原 | 200 | − | − | − | ||||||||
| 箱根湯本 | − | − | − | |||||||||
| 箱根湯本 | − | − | − | |||||||||
| 大和 | 450 | 450 | ||||||||||
| 大和 | 500 | 500 | ||||||||||
| 藤沢 | 450 | |||||||||||
| 藤沢 | 500 | |||||||||||
| 片瀬江ノ島 |
| 新宿 | 450 | 450 | 450 | 600 | 600 | 700 | 700 | 950 | 1,150 | 600 | 700 | 700 | |
| 新宿 | 500 | 500 | 650 | 650 | 750 | 750 | 1,000 | 1,200 | 650 | 750 | 750 | ||
| 新百 合ヶ丘 | 450 | 450 | 450 | 450 | 450 | 600 | 700 | 900 | 450 | 450 | 600 | ||
| 新百 合ヶ丘 | 500 | 500 | 500 | 500 | 500 | 650 | 750 | 950 | 500 | 500 | 650 | ||
| 町田 | 450 | 450 | 450 | 450 | 450 | 700 | 900 | — | — | — | |||
| 町田 | 500 | 500 | 500 | 500 | 500 | 500 | 750 | 950 | — | — | — | ||
| 相模大野 | 450 | 450 | 450 | 450 | 700 | 900 | 450 | 450 | 450 | ||||
| 相模大野 | 500 | 500 | 500 | 500 | 750 | 950 | 500 | 500 | 500 | ||||
| 海老名 | 450 | 450 | 450 | 600 | 800 | — | — | — | |||||
| 海老名 | 500 | 500 | 500 | 650 | 850 | — | — | — | |||||
| 本厚木 | 450 | 450 | 600 | 800 | — | — | — | ||||||
| 本厚木 | 500 | 500 | 650 | 850 | — | — | — | ||||||
| 伊勢原 | 450 | 450 | 650 | — | — | — | |||||||
| 伊勢原 | 500 | 500 | 700 | — | — | — | |||||||
| 秦野 | 450 | 650 | — | — | — | ||||||||
| 秦野 | 500 | 700 | — | — | — | ||||||||
| 小田原 | - | — | — | — | |||||||||
| 小田原 | 200 | — | — | — | |||||||||
| 箱根 湯本 | — | — | — | ||||||||||
| 箱根 湯本 | — | — | — | ||||||||||
| 大和 | 450 | 450 | |||||||||||
| 大和 | 500 | 500 | |||||||||||
| 藤沢 | 450 | ||||||||||||
| 藤沢 | 500 | ||||||||||||
| 片瀬 江ノ島 | |||||||||||||
| 上段 | チケットレス特別急行料金 大人 | ||||||||||||
| 下段 | 特別急行料金 大人 |
| 新宿 | 450 | 450 | 450 | 600 | 600 | 700 | 700 | 950 | 1,150 | 600 | 700 | 700 |
| 新宿 | 500 | 500 | 500 | 650 | 650 | 750 | 750 | 1,000 | 1,200 | 650 | 750 | 750 |
| 新百合ヶ丘 | 450 | 450 | 450 | 450 | 450 | 600 | 700 | 900 | 450 | 450 | 600 | |
| 新百合ヶ丘 | 500 | 500 | 500 | 500 | 500 | 650 | 750 | 950 | 500 | 500 | 650 | |
| 町田 | 450 | 450 | 450 | 450 | 450 | 700 | 900 | — | — | — | ||
| 町田 | 500 | 500 | 500 | 500 | 500 | 750 | 950 | — | — | — | ||
| 相模大野 | 450 | 450 | 450 | 450 | 450 | 700 | 900 | 450 | 450 | 450 | ||
| 相模大野 | 500 | 500 | 500 | 500 | 500 | 750 | 950 | 500 | 500 | 500 | ||
| 海老名 | 450 | 450 | 450 | 450 | 600 | 600 | 800 | — | — | — | ||
| 海老名 | 500 | 500 | 500 | 500 | 650 | 650 | 850 | — | — | — | ||
| 本厚木 | 450 | 450 | 450 | 600 | 600 | 800 | — | — | — | |||
| 本厚木 | 500 | 500 | 500 | 650 | 650 | 850 | — | — | — | |||
| 伊勢原 | 450 | 450 | 450 | 650 | — | — | — | |||||
| 伊勢原 | 500 | 500 | 500 | 700 | — | — | — | |||||
| 秦野 | 450 | 450 | 650 | — | — | — | ||||||
| 秦野 | 500 | 500 | 700 | — | — | — | ||||||
| 小田原 | — | — | — | — | ||||||||
| 小田原 | 200 | — | — | — | ||||||||
| 箱根湯本 | — | — | — | |||||||||
| 大和 | 450 | 450 | ||||||||||
| 大和 | 500 | 500 | ||||||||||
| 藤沢 | 450 | |||||||||||
| 藤沢 | 500 | |||||||||||
| 片瀬江ノ島 |
| 新宿 | 450 | 450 | 450 | 600 | 600 | 700 | 700 | 950 | 1,150 | 600 | 700 | 700 |
| 500 | 500 | 500 | 650 | 650 | 750 | 750 | 1,000 | 1,200 | 650 | 750 | 750 | |
| 新百合ヶ丘 | 450 | 450 | 450 | 450 | 450 | 450 | 600 | 700 | 900 | 450 | 450 | 600 |
| 500 | 500 | 500 | 500 | 500 | 500 | 650 | 750 | 950 | 500 | 500 | 650 | |
| 町田 | 450 | 450 | 450 | 450 | 450 | 450 | 700 | 900 | 900 | 450 | 450 | 450 |
| 500 | 500 | 500 | 500 | 500 | 500 | 750 | 950 | 950 | 500 | 500 | 500 | |
| 相模大野 | 450 | 450 | 450 | 450 | 450 | 450 | 600 | 800 | 800 | 450 | 450 | 450 |
| 500 | 500 | 500 | 500 | 500 | 500 | 750 | 950 | 950 | 500 | 500 | 500 | |
| 海老名 | 450 | 450 | 450 | 450 | 450 | 450 | 600 | 800 | 800 | 450 | 450 | 450 |
| 500 | 500 | 500 | 500 | 500 | 500 | 650 | 850 | 850 | 500 | 500 | 500 | |
| 本厚木 | 450 | 450 | 450 | 600 | 800 | 800 | 800 | 800 | 800 | 450 | 450 | 450 |
| 500 | 500 | 500 | 650 | 850 | 850 | 850 | 850 | 850 | 500 | 500 | 500 | |
| 伊勢原 | 500 | 500 | 500 | 700 | 700 | 700 | 700 | 700 | 700 | 500 | 500 | 500 |
| 秦野 | 450 | 450 | 450 | 600 | 700 | 700 | 700 | 700 | 700 | 500 | 500 | 500 |
| 小田原 | 200 | 200 | 200 | 200 | 200 | 200 | 200 | 200 | 200 | 200 | 200 | 200 |
| 箱根湯本 | 450 | 450 | 450 | 450 | 450 | 450 | 450 | 450 | 450 | 450 | 450 | 450 |
| 大和 | 500 | 500 | 500 | 500 | 500 | 500 | 500 | 500 | 500 | 500 | 500 | 500 |
| 藤沢 | 500 | 500 | 500 | 500 | 500 | 500 | 500 | 500 | 500 | 500 | 500 | 500 |
| 片瀬江ノ島 |
Limited-express fares (lower): from Kita-Senju
| 北千住〜小田原・箱根湯本 | 北千住〜片瀬江ノ島 | ||||||||||||||||
| 北千住 | 660 710 | 660 710 | 660 710 | 660 710 | 810 860 | 810 860 | 810 860 | 1,160 1,210 | 1,360 1,410 | 910 960 | 910 960 | ||||||
| 大手町 | 660 710 | 660 710 | 660 710 | 660 710 | 810 860 | 810 860 | 810 860 | 1,160 1,210 | 1,360 1,410 | 910 960 | 910 960 | ||||||
| 甕ケ間 | 660 710 | 660 710 | 660 710 | 660 710 | 810 860 | 810 860 | 810 860 | 1,160 1,210 | 1,360 1,410 | 910 960 | 910 960 | ||||||
| 表参道 | 660 710 | 660 710 | 660 710 | 660 710 | 810 860 | 810 860 | 810 860 | 1,160 1,210 | 1,360 1,410 | 910 960 | 910 960 | ||||||
| 450 500 | 450 500 | 450 500 | 450 500 | 600 650 | 700 750 | 900 950 | 600 650 | 600 650 | |||||||||
| 成城学園前 | |||||||||||||||||
| 450 500 | 450 500 | 450 500 | 450 500 | 600 650 | 700 750 | 900 950 | |||||||||||
| 新百合ヶ丘 | |||||||||||||||||
| 450 500 | 450 500 | 450 500 | 450 500 | 600 650 | 700 750 | 900 950 | |||||||||||
| 町田 | |||||||||||||||||
| 450 500 | 450 500 | 450 500 | 450 500 | 600 650 | 700 750 | 900 950 | |||||||||||
| 相模大野 | |||||||||||||||||
| 450 500 | 450 500 | 450 500 | 450 500 | 600 650 | 700 750 | 900 950 | 450 500 | 450 500 | |||||||||
| 海老名 | |||||||||||||||||
| 450 500 | 450 500 | 450 500 | 450 500 | 600 650 | 700 750 | 800 850 | |||||||||||
| 本厚木 | |||||||||||||||||
| 450 500 | 450 500 | 450 500 | 450 500 | 600 650 | 700 750 | 800 850 | |||||||||||
| 伊勢原 | |||||||||||||||||
| 450 500 | 450 500 | 450 500 | 450 500 | 650 700 | |||||||||||||
| 小田原 | |||||||||||||||||
| ー 200 | |||||||||||||||||
| 箱根湯本 | |||||||||||||||||
| ー | |||||||||||||||||
| 藤沢 | |||||||||||||||||
| 450 500 | |||||||||||||||||
| 片瀬江ノ島 |
| 北千住 | 660 710 | 660 710 | 660 710 | 660 710 | 810 860 | 810 860 | 810 860 | 1,160 1,210 | 1,360 1,410 | 910 960 | 910 960 |
| 大手町 | 660 710 | 660 710 | 660 710 | 660 710 | 810 860 | 810 860 | 810 860 | 1,160 1,210 | 1,360 1,410 | 910 960 | 910 960 |
| 霞ヶ関 | 660 710 | 660 710 | 660 710 | 660 710 | 810 860 | 810 860 | 810 860 | 1,160 1,210 | 1,360 1,410 | 910 960 | 910 960 |
| 表参道 | 660 710 | 660 710 | 660 710 | 660 710 | 810 860 | 810 860 | 810 860 | 1,160 1,210 | 1,360 1,410 | 910 960 | 910 960 |
| 成城 学園前 | 450 500 | 450 500 | 450 500 | 450 500 | 450 500 | 600 650 | 700 750 | 900 950 | 600 650 | 600 650 | |
| 新百 合ヶ丘 | 450 500 | 450 500 | 450 500 | 450 500 | 450 500 | 700 750 | 900 950 | — | — | ||
| 町田 | 450 500 | 450 500 | 450 500 | 450 500 | 700 750 | 900 950 | — | — | |||
| 相模 大野 | 450 500 | 450 500 | 450 500 | 700 750 | 900 950 | 450 500 | 450 500 | ||||
| 海老名 | 450 500 | 600 650 | 800 850 | — | — | ||||||
| 本厚木 | 450 650 | 600 850 | — | — | |||||||
| 伊勢原 | 450 500 | 650 700 | — | — | |||||||
| 小田原 | — 200 | — | — | ||||||||
| 箱根湯本 | — | — | |||||||||
| 藤沢 | 450 500 | ||||||||||
| 片瀬 江ノ島 |
| 北千住 | 660 710 | 660 710 | 660 710 | 660 710 | 810 860 | 810 860 | 810 860 | 1,160 1,210 | 1,360 1,410 | 910 960 | 910 960 |
| 大手町 | 660 710 | 660 710 | 660 710 | 660 710 | 810 860 | 810 860 | 810 860 | 1,160 1,210 | 1,360 1,410 | 910 960 | 910 960 |
| 霞ヶ関 | 660 710 | 660 710 | 660 710 | 660 710 | 810 860 | 810 860 | 810 860 | 1,160 1,210 | 1,360 1,410 | 910 960 | 910 960 |
| 表参道 | 660 710 | 660 710 | 660 710 | 660 710 | 810 860 | 810 860 | 810 860 | 1,160 1,210 | 1,360 1,410 | 910 960 | 910 960 |
| 成城学園前 | 成城学園前 | 450 500 | 450 500 | 450 500 | 450 500 | 450 500 | 600 650 | 700 750 | 900 950 | 600 650 | 600 650 |
| 新百合ヶ丘 | 新百合ヶ丘 | 450 500 | 450 500 | 450 500 | 450 500 | 450 500 | 700 750 | 900 950 | — | — | |
| 町田 | 町田 | 町田 | 450 500 | 450 500 | 450 500 | 450 500 | 700 750 | 900 950 | — | — | |
| 相模大野 | 相模大野 | 相模大野 | 相模大野 | 450 500 | 450 500 | 450 500 | 450 500 | 700 750 | 900 950 | 450 450 | 450 450 |
| 海老名 | 海老名 | 海老名 | 海老名 | 海老名 | 450 500 | 450 500 | 450 500 | 450 500 | 600 650 | 800 850 | — |
| 本厚木 | 本厚木 | 本厚木 | 本厚木 | 本厚木 | 本厚木 | 450 500 | 450 500 | 450 500 | 600 650 | 800 850 | — |
| 伊勢原 | 伊勢原 | 伊勢原 | 伊勢原 | 伊勢原 | 伊勢原 | 伊勢原 | 450 500 | 450 500 | 450 500 | 650 700 | — |
| 小田原 | 小田原 | 小田原 | 小田原 | 小田原 | 小田原 | 小田原 | 小田原 | 450 500 | 450 500 | — 200 | — |
| 箱根湯本 | 箱根湯本 | 箱根湯本 | 箱根湯本 | 箱根湯本 | 箱根湯本 | 箱根湯本 | 箱根湯本 | 箱根湯本 | — | — | |
| 藤沢 | 藤沢 | 藤沢 | 藤沢 | 藤沢 | 藤沢 | 藤沢 | 藤沢 | 藤沢 | 藤沢 | 450 500 | |
| 片瀬江/島 | 片瀬江/島 | 片瀬江/島 | 片瀬江/島 | 片瀬江/島 | 片瀬江/島 | 片瀬江/島 | 片瀬江/島 | 片瀬江/島 | 片瀬江/島 | 片瀬江/島 | 片瀬江/島 |
| 北千住 | 660 710 | 660 710 | 660 710 | 660 710 | 810 860 | 810 860 | 810 860 | 1,160 1,210 | 1,360 1,410 | 910 960 | 910 960 |
| 大手町 | 660 710 | 660 710 | 660 710 | 660 710 | 810 860 | 810 860 | 810 860 | 1,160 1,210 | 1,360 1,410 | 910 960 | 910 960 |
| 霞ヶ関 | 660 710 | 660 710 | 660 710 | 660 710 | 810 860 | 810 860 | 810 860 | 1,160 1,210 | 1,360 1,410 | 910 960 | 910 960 |
| 表参道 | 660 710 | 660 710 | 660 710 | 660 710 | 810 860 | 810 860 | 810 860 | 1,160 1,210 | 1,360 1,410 | 910 960 | 910 960 |
| 成城 学園前 | 450 500 | 450 500 | 450 500 | 450 500 | 450 500 | 600 650 | 700 750 | 900 950 | 600 650 | 600 650 | |
| 新百 合ヶ丘 | 450 500 | 450 500 | 450 500 | 450 500 | 450 500 | 700 900 | 900 950 | - | - | ||
| 町田 | 450 500 | 450 500 | 450 500 | 450 500 | 700 750 | 900 950 | - | - | |||
| 相模 大野 | 450 500 | 450 500 | 450 500 | 700 750 | 900 950 | 450 500 | 450 500 | ||||
| 海老名 | 450 500 | 450 500 | 600 650 | 800 850 | - | - | |||||
| 本厚木 | 450 500 | 600 650 | 800 850 | - | - | ||||||
| 伊勢原 | 450 500 | 650 700 | - | - | |||||||
| 小田原 | - 200 | - | - | ||||||||
| 箱根湯本 | - | - | |||||||||
| 藤沢 | 450 500 | ||||||||||
| 片瀬 江ノ島 |
| 北千住 | 660 | 660 | 660 | 660 | 810 | 810 | 810 | 1,160 | 1,360 | 910 | 910 |
| 710 | 710 | 710 | 710 | 860 | 860 | 860 | 1,210 | 1,410 | 960 | 960 | |
| 大手町 | 660 | 660 | 660 | 660 | 810 | 810 | 810 | 1,160 | 1,360 | 910 | 910 |
| 710 | 710 | 710 | 710 | 860 | 860 | 860 | 1,210 | 1,410 | 960 | 960 | |
| 霞ヶ関 | 660 | 660 | 660 | 660 | 810 | 810 | 810 | 1,160 | 1,360 | 910 | 910 |
| 710 | 710 | 710 | 710 | 860 | 860 | 860 | 1,210 | 1,410 | 960 | 960 | |
| 表参道 | 660 | 660 | 660 | 660 | 810 | 810 | 810 | 1,160 | 1,360 | 910 | 910 |
| 710 | 710 | 710 | 710 | 860 | 860 | 860 | 1,210 | 1,410 | 960 | 960 | |
| 成城学園前 | 450 | 450 | 450 | 450 | 450 | 450 | 600 | 700 | 900 | 600 | 600 |
| 500 | 500 | 500 | 500 | 500 | 500 | 650 | 750 | 950 | 650 | 650 | |
| 新百合ヶ丘 | 450 | 450 | 450 | 450 | 450 | 450 | 700 | 900 | — | — | |
| 500 | 500 | 500 | 500 | 500 | 500 | 750 | 950 | — | — | ||
| 町田 | 450 | 450 | 450 | 450 | 450 | 450 | 700 | 900 | — | — | |
| 500 | 500 | 500 | 500 | 500 | 500 | 750 | 950 | — | — | ||
| 相模大野 | 450 | 450 | 450 | 450 | 450 | 450 | 700 | 900 | 450 | 450 | |
| 500 | 500 | 500 | 500 | 500 | 500 | 750 | 950 | 500 | 500 | ||
| 海老名 | 450 | 450 | 450 | 600 | 800 | — | — | ||||
| 500 | 500 | 500 | 650 | 850 | — | — | |||||
| 本厚木 | 450 | 450 | 600 | 800 | — | — | |||||
| 500 | 500 | 650 | 850 | — | — | ||||||
| 伊勢原 | 450 | 450 | 650 | — | — | ||||||
| 500 | 500 | 700 | — | — | |||||||
| 小田原 | — | 200 | — | — | |||||||
| 箱根湯本 | — | — | |||||||||
| 藤沢 | 450 | ||||||||||
| 500 | |||||||||||
| 片瀬江ノ島 |
| 北千住 | 660 | 660 | 660 | 660 | 810 | 810 | 1,160 | 1,360 | 910 | 910 | |
| 710 | 710 | 710 | 710 | 860 | 860 | 1,210 | 1,410 | 960 | 960 | ||
| 大手町 | 660 | 660 | 660 | 660 | 810 | 810 | 1,160 | 1,360 | 910 | 910 | |
| 710 | 710 | 710 | 710 | 860 | 860 | 1,210 | 1,410 | 960 | 960 | ||
| 霞ヶ関 | 660 | 660 | 660 | 660 | 810 | 810 | 1,160 | 1,360 | 910 | 910 | |
| 710 | 710 | 710 | 710 | 860 | 860 | 1,210 | 1,410 | 960 | 960 | ||
| 表参道 | 660 | 660 | 660 | 660 | 810 | 810 | 1,160 | 1,360 | 910 | 910 | |
| 710 | 710 | 710 | 710 | 860 | 860 | 1,210 | 1,410 | 960 | 960 | ||
| 成城学園前 | 450 | 450 | 450 | 450 | 450 | 600 | 700 | 900 | 600 | 600 | |
| 500 | 500 | 500 | 500 | 500 | 650 | 750 | 950 | 650 | 650 | ||
| 新百合ヶ丘 | 450 | 450 | 450 | 450 | 450 | 700 | 900 | 900 | 450 | 450 | |
| 500 | 500 | 500 | 500 | 500 | 750 | 950 | 950 | 500 | 500 | ||
| 町田 | 450 | 450 | 450 | 450 | 450 | 700 | 900 | 900 | 450 | 450 | |
| 500 | 500 | 500 | 500 | 500 | 750 | 950 | 950 | 500 | 500 | ||
| 相模大野 | 450 | 450 | 450 | 450 | 450 | 700 | 900 | 900 | 450 | 450 | |
| 500 | 500 | 500 | 500 | 500 | 750 | 950 | 950 | 500 | 500 | ||
| 海老名 | 450 | 450 | 450 | 450 | 450 | 700 | 900 | 900 | 450 | 450 | |
| 500 | 500 | 500 | 500 | 500 | 750 | 950 | 950 | 500 | 500 | ||
| 本厚木 | 450 | 450 | 450 | 600 | 800 | 800 | 800 | 800 | 800 | 450 | 450 |
| 500 | 500 | 500 | 650 | 850 | 850 | 850 | 850 | 850 | 500 | 500 | |
| 伊勢原 | 500 | 500 | 500 | 700 | 700 | 700 | 700 | 700 | 700 | 500 | 500 |
| 小田原 | 200 | 200 | 200 | 200 | 200 | 200 | 200 | 200 | 200 | 200 | 200 |
| 箱根湯本 | 450 | 450 | 450 | 450 | 450 | 450 | 450 | 450 | 450 | 450 | 450 |
| 藤沢 | 450 | 450 | 450 | 450 | 450 | 450 | 450 | 450 | 450 | 450 | 450 |
| 片瀬江ノ島 | |||||||||||
| 92 |
- On the lower table the models differ sharply. gemma kept copying one pattern down the staircase part, ending with 56 errors, and flagged its own reading as unreadable. Qwen without thinking made 4 errors.
- Strong thinking made this table worse. The same Qwen at strength 3 made 20 errors and took about 14 times as long. With prompt A it made 1 error, but took even longer.
- The much larger DeepSeek made more errors on this table. At strength 0 it made 36 across both tables (Qwen: 6). On the other 8 tables it was as good as Qwen or better, for example leaving merged cells empty as the reference does. At strength 1 the errors rose to 57, and each table took about 19 minutes. DeepSeek was measured on 4 November 2026, with a newer Strata version on a different PC.
- The vision model used before Strata lost the shape of the table. It wrote the staircase table as a rectangle with rows of equal length and repeated values, for 118 errors on the upper table and 96 on the lower. It read the whole page in one pass, with a different image and prompt from the readings above, so what compares is whether the shape of the table survived.
Thinking strength and accuracy
The two hardest limited-express fare tables (48 fare rows) were read with different thinking strengths, prompts and repeats. Then the strength was varied for the RAG answers too.
Transcribing a table
| Setting | Errors (2 tables) | Time (2 tables) |
|---|---|---|
| gemma, strength 0 | 56 | 139 s |
| Qwen, strength 0 | 6 | 147 s |
| Strength 0, prompt B | 4 | 161 s |
| Strength 0, prompt A | 4 | 125 s |
| Strength 1 | 4 → 17 (same setting, twice) | about 310 s |
| Strength 1, prompt B | 7 | 623 s |
| Strength 1, prompt A | 7 | 341 s |
| Strength 2 | 5 | 517 s |
| Strength 3 | 32 | 1,987 s |
| Strength 3, prompt A | 3 | 2,383 s |
| DeepSeek, strength 0 | 36 | 166 s |
| DeepSeek, strength 1 | 57 | 2,286 s |
With a little randomness (temperature 0.6) and three runs of each setting, the spread becomes visible.
| Setting (temperature 0.6) | Run 1 | Run 2 | Run 3 |
|---|---|---|---|
| Strength 0 | 7 | 40 | 73 |
| Strength 1 | 4 | 4 | 16 |
- Time and errors are not proportional. Strength 3, the longest, produced both the worst result (32) and some of the best (1–3).
- What light thinking did was narrow the spread. With randomness, strength 0 sometimes collapsed badly (73); strength 1 collapsed less. It cut the worst case more than it raised the average.
- Temperature 0 does not guarantee the same result. Two runs with the same setting gave 4 and 17 errors. A single run says very little.
Inside a long thinking run
We saved the thinking of a strength-3 run that took about 18 minutes. A passage of about 1,400 characters was repeated word for word 16 times, until the server closed the thinking. Every draft written inside the loop was identical to the final answer.
It kept asking "which row is this table's header?" and "which side is the origin and which the destination?". This fare table has no header row, so the question had no answer and the model circled the same check. The answer had been settled in roughly the first tenth of the thinking.
Answering questions
On the same source, Qwen answered three questions of different kinds.
| Question | Strength 0 | Strength 1 (3 runs) | Strength 3 |
|---|---|---|---|
| "I attend a correspondence high school. Can I buy a student commuter pass?" (apply a rule) | 63–88 s. Did not decide; one run correctly showed the exclusion clause (good answer) | 102–133 s. "No" all three times, stated firmly (wrong) | 440 s. Did not decide |
| "What is the operating distance from Shinjuku to Minami-Shinjuku?" (look up) | 43 s. Right | 47 s. Right | — |
| "What is the ticketless limited-express fee from Kita-Senju to Hon-Atsugi?" (read a fare table) | 47 s. Declined: "the table's columns can't be identified" | 549–1,247 s. Right 2 of 3; once the value of another column | 1,159 s. Right number, wrong explanation |
- Light thinking hardened a mistake with plausible reasoning. It explained "correspondence students have a separate discount scheme, so they are not covered by the commuter pass" and stated it firmly without checking the exclusion clause. The same mistake all three times.
- No thinking and strong thinking did not decide. On this question that is the good answer. One run without thinking correctly noted that "only item 1 (the university) is excluded". Strong thinking took more than three times as long as strength 1.
- The fare question was not one for thinking to solve. As the next section shows, the cause was in the source text.
The real cause of the wrong fare answer
The wrong and the right runs received the same evidence (the same eight passages in the same order). They differed only in how the model guessed the table's columns.
- The printed fare table has no header row of destinations. Several origin rows share the first column, then each station's name moves one column right: a "staircase". Each column's station is printed at the foot of that column, on the diagonal.
- The reading itself was right. In the stored table the station names sit at the correct diagonal positions, and the right answer follows from the data alone.
- The meaning was lost when the table became search text. The band title was copied into every column as a header, which looks like a header but says nothing. The table was also split into several passages, and a station's column was shown only by how many empty cells came before it.
- So the answering model had to guess the column order. The wrong run took the origin rows for destination columns, never recovered, and was cut off at the thinking limit. One of the right runs reached its answer only just before that limit.
The fix and its result
At ingestion, staircase tables are now detected and stored one pair per line, such as "Kita-Senju → Hon-Atsugi: 810". Detection uses only the table's shape, never station names, units or other content of this source.
| Kita-Senju to Hon-Atsugi fee | Before | After |
|---|---|---|
| Strength 0 | 47 s. Declined | 18–45 s. Right (3 runs) |
| Strength 1 | 549–1,247 s. Right 2 of 3 | 99 s. Right |
- Generality was checked on made-up tables. Seven kinds of invented staircases (cities, teams and so on) were rewritten correctly, and nine look-alikes (plain tables, two-level row headers, chapter/section/article outlines, timetables and more) were left alone. The first test run caught an outline being taken for a staircase; a condition was added to fix it.
- In this source, only 3 of 46 tables were newly detected, all fare tables. Four square tables were already stored as pairs.
- Human-approved formatting is kept. When the search-text version changes, accepted formatting (22 passages) moves over to every passage whose source text is unchanged.
Comparing answer models: Qwen and DeepSeek
We swapped the answer model for another, much larger model that also runs on Strata, DeepSeek-V4.1-Flash and asked 14 questions on the same source (the version with the tables fixed). The right answers were taken from the rule text before asking. Both models ran at strength 0.
| Question | Right answer (rule text) | Qwen | DeepSeek |
|---|---|---|---|
| Ticketless limited-express fee, Kita-Senju to Hon-Atsugi | 810 yen | right · 45 s | right · 83 s |
| Operating kilometres, Shinjuku to Minami-Shinjuku | 0.8 km | right · 34 s | right · 50 s |
| Can a correspondence high-school student buy a student commuter pass? | the document alone does not decide (not ruled out by the text; the discounted tickets can be bought) | did not decide, showed that only university students are excluded (good answer) · 63 s | did not decide (without the exclusion clause) · 87 s |
| Student pass for a 10-year-old, 3 months | 2,280 yen | right · 57 s | gave the number, then left it open · 169 s |
| One adult with three 5-year-olds | two free, one pays the child fare | right · 51 s | right · 136 s |
| Platform ticket | adult 140 yen, child 70 yen | right · 27 s | right · 108 s |
| Refund fee for an unused ordinary ticket | 100 yen (through ticket 220 yen) | right · 34 s | right · 122 s |
| Limited-express ticket refund: deadline and fee | until the train leaves · 100 yen | right · 37 s | right · 135 s |
| Fractions of a kilometre | rounded up to 1 km | right · 24 s | right · 114 s |
| Barrier-free surcharge on a commuter pass | 600 yen a month | right · 24 s | right · 115 s |
| Ticket expires during the journey | valid to the destination if you do not break the journey | right · 46 s | right · 139 s |
| Can I take my cat in a carrier? | yes (free, sides up to 120 cm in total, up to 10 kg) | right · 38 s | conditions right, then left it open · 170 s |
| How many suitcases can I bring free? | two (up to 30 kg, up to 2 m long) | right · 24 s | conditions right, then left it open · 134 s |
| Refund fee for a commuter pass before its start date | 220 yen | right · 24 s | right · 111 s |
- The larger model did not answer more questions right. DeepSeek left the answer open whenever the evidence did not use the question's own words: the rules never say "suitcase", and the evidence it received did not say that a cat is a "small animal" or that a 10-year-old is a "child". The content was right every time, and it never stated a wrong answer.
- Thinking did not change DeepSeek's answers. We also ran the first three questions at strength 1: the answers were the same as at strength 0, only 1.3 to 6 times slower. The correspondence-school question stayed undecided.
- DeepSeek is slow because of this PC. Most of the model fits neither in the GPUs nor in RAM: each token read about 250 MB from the SSD and computed the rest on the 6-core CPU. On one GPU it generated 2.4 tokens/s. Split over both GPUs with more of it kept in RAM, it reached 3.7 tokens/s and answered 2.3 to 2.8 times faster.
- On this source and this PC, Qwen is the better answer model. It answers more questions right and decisively, and is 3 to 4 times faster. DeepSeek's strength is that it never stated a wrong answer; Qwen at strength 1 stated the same wrong answer three times.
Recheck on 4 November: a newer version, and instructions for any document
We asked the same questions again with Strata 0.2.10 on a PC with two CPUs. We also added two instructions meant for any document to the answer prompt and tested whether they help. Instructions tuned to one document were not allowed.
The correspondence-school question depends on interpretation
Reading the articles again: the commuter-pass article excludes only students of the correspondence university, not correspondence high-school students. Whether such a student can actually buy a commuter pass, however, depends on the school (whether it is a designated school and issues a commuting certificate) and on the railway's practice. In practice, the right answer is that this document alone does not decide it. So we scored every answer to this question again. A good answer shows that the discounted tickets can be bought and that the commuter pass is not ruled out by the text (it depends on the school), without deciding. An answer that states "no" firmly is wrong.
| Condition | Strata | Runs | Good answer | Undecided but incomplete | Stated "no" firmly |
|---|---|---|---|---|---|
| Qwen, strength 0 | 0.2.4.2 | 2 | 1 | 1 | 0 |
| Qwen, strength 1 | 0.2.4.2 | 3 | 0 | 0 | 3 |
| Qwen, strength 3 | 0.2.4.2 | 1 | 0 | 1 | 0 |
| DeepSeek, strengths 0 and 1 | 0.2.4.2 | 4 | 0 | 4 | 0 |
| Qwen, strength 0 | 0.2.9 | 4 | 0 | 0 | 4 |
| Qwen, strength 0 | 0.2.10 | 3 | 2 | 1 | 0 |
| Qwen, strength 1 | 0.2.10 | 3 | 1 | 0 | 2 |
| DeepSeek, strength 0 | 0.2.10 | 3 | 0 | 3 | 0 |
| DeepSeek, strength 1 | 0.2.10 | 3 | 2 | 1 | 0 |
| llm-jp (the answer model before Strata) | before | 3 | 0 | 3 | 0 |
- Thinking still made firm statements more likely on the newer version. Qwen at strength 1 stated "no" firmly in 5 of 6 runs.
- Even Qwen at strength 0 answered differently by version and day. On 0.2.10, 2 of 3 runs were good answers; on 0.2.9 all 4 said "no". Too few runs to blame the version.
- DeepSeek never stated a conclusion firmly. On 0.2.10 at strength 1 it also showed that only university students are excluded.
Other questions and speed
- The fare, the distance and the other 11 questions got the same answers as before (Qwen right and decisive on all 13, DeepSeek left 3 open).
- The mean time for the 11 questions fell to 26 s for Qwen (35 s before) and 52 s for DeepSeek (132 s before): on this PC most of DeepSeek's weights fit in RAM.
- In table reading, DeepSeek was the most accurate on ordinary tables but made many errors on the staircase fare tables (see the list below).
Adding instructions meant for any document
We added two instructions to the answer prompt. Instruction 1: do not conclude "cannot" unless the evidence clearly states a prohibition or exclusion, and separate what is written from what is not. Instruction 2: when a general rule and a rule for a specific case appear together, do not treat the specific rule as overriding the general one beyond what it says. Besides this source, we used 14 questions on a home-appliance manual (204 pages) that was not looked at while writing the instructions. Right answers were fixed from the text before asking.
| Setting (Qwen, strength 0, 0.2.9) | Manual, 14 questions | This source, 13 questions | Correspondence question (3 runs) |
|---|---|---|---|
| Current prompt | 14 | 13 | "no" all three times |
| Instruction 1 | 14 | 13 | "you buy the discounted tickets instead" all three times |
| Instruction 2 | 14 | 12 | "you buy the discounted tickets instead" all three times |
| Instructions 1 and 2 | 14 | 13 | "you buy the discounted tickets instead" all three times |
- Neither instruction helped. With instruction 1 the words "cannot buy" disappeared, but the answer became "you buy the discounted tickets instead of a commuter pass": the same conclusion in other words.
- Instruction 2 made one answer worse. On the three-infants question it left out the key point that the third child pays a fare and added a guess.
- The manual showed no difference. The current prompt already answered all 14 right. The instructions did not make the model hedge on things the manual clearly forbids, and for things it does not mention (wireless earphones, a video service, smartphones) every setting answered "not stated".
- The prompts in use do not depend on the document. We checked the prompts for answering, planning the search, cleaning the text and reading tables: no prompt contains words from this source. Of the measures made from this source, prompt A's example and the "origin → destination" rewrite of staircase tables still carry the idea of a fare table.
Recheck on 5 November: on another PC, the interpretive question got different answers
We raised the earlier PC (Core i7-7800X, "i7" below) to 125 GiB of RAM and moved the two GPUs from the two-CPU PC into it. Then we ran the same Strata 0.2.10, settings, index and questions as on 4 November. Only the PC was different.
| Setting | 13 questions besides the correspondence one: right and decisive | Mean time, 11 questions | Correspondence: good answers | Correspondence: firm "cannot buy" |
|---|---|---|---|---|
| Qwen, strength 0 | 13 (13) | 19 s (26 s) | 0 (2) | 3 (0) |
| Qwen, strength 1 | — | — | 0 (1) | 3 (2) |
| DeepSeek, strength 0 | 11 (10) | 46 s (52 s) | 2 (0) | 0 (0) |
| DeepSeek, strength 1 | — | — | 2 (2) | 0 (0) |
| llm-jp (the answer model before Strata) | 11 (11) | 28 s (39 s) | 0 (0) | 3 (0) |
- Table reading and the factual questions came out almost the same. In table reading (F1 over the 10 crops), Qwen matched at 0.85, and DeepSeek scored 0.86 (0.88 before). Qwen answered all 13 factual questions right and decisively. DeepSeek answered one more of them decisively than before and left 2 open.
- Answers were 10–30% faster. Most of the answer time is the search on the CPU, so we think the i7's faster single core helped, but we have not checked this. Qwen's table reading, on the other hand, took 100 s a crop, 16% slower than before. We have not looked into why.
- On the correspondence question, Qwen and llm-jp said "cannot buy" firmly all 3 times. On the two-CPU PC, Qwen at strength 0 gave the good answer in 2 of 3 runs, and llm-jp gave a conditional answer all 3 times. The weights were the same and the temperature was 0; only the PC was different. For llm-jp the output differed from the very first step, where the question is split into parts, and some of the evidence it found changed too. Even at temperature 0, a different PC can give a different answer.
- DeepSeek again never said "cannot buy" firmly. That makes 16 runs on two PCs. On the i7, 2 runs at each of strengths 0 and 1 gave the good answer: they showed that only university students are excluded, or that it depends on whether the school is a designated one.
- llm-jp's answer to the three-infants question changed. On the two-CPU PC it was cut off at the answer length limit. On the i7 an answer came back, but it was wrong: it treated a 5-year-old as a child fare.
- The overall verdict does not change. The system is usable for looking up facts, but not yet reliable on questions that depend on interpretation. DeepSeek's experts did not fit in 125 GiB of RAM either, and part of them was read from the SSD, yet its answers were faster than before.
Evening of 5 November: switching Qwen's experts to 4-bit NVFP4 did not change answer quality
We swapped Qwen3.8-Flash-Next's experts from UD-Q4_K_XL to NVFP4 (NVIDIA's 4-bit format, in the GPTQ pack made for Strata). The experts get 12% smaller, which makes long prompts and decoding faster (research page). To see whether the smaller weights cost answer quality, we compared the two on the same i7 PC with the same index and questions, in the same session. Both used the faster layer split found earlier that day.
| Check | UD-Q4_K_XL | NVFP4 |
|---|---|---|
| 13 questions besides the correspondence one: right and decisive (strength 0) | 13 | 13 |
| Mean time, 11 questions (strength 0) | 16 s | 15 s |
| Correspondence: good answers / runs (strength 0) | 0 / 3 | 0 / 3 |
| Correspondence: good answers / runs (strength 1) | 0 / 5 | 0 / 5 (one run hedged: "the material does not settle it") |
| Table reading: F1 over 10 crops | 0.87 | 0.87 |
| Table reading: mean per crop | 95 s | 87 s |
| Staircase fare table errors (strength 0, upper + lower) | 1 + 2 | 3 + 0 |
| Staircase fare table errors (strength 1, upper + lower) | 1 + 7 | 1 + 0 |
- Both answered all 13 factual questions right and decisively. The answers said the same things (amounts, conditions, conclusions) and differed only in wording. The model does the first step of splitting the question, so the retrieved evidence changed for about half the questions, but the scores did not.
- Table reading was the same too. Errors on the staircase fare table move between 0 and 7 from run to run. NVFP4 had fewer this time, but with one run each that is within the spread.
- On the correspondence question, both mostly said firmly "buy the discounted tickets", also at strength 1. One NVFP4 run showed that only university students are excluded and correspondence high schools are not named, and said the material does not settle whether a commuter pass can be bought. Its first sentence still asserted the tickets, so we did not count it as a good answer. UD also had a run that quoted the exclusion correctly and then asserted the tickets.
- NVFP4 was faster. Answers took about 10% less time per question and table reading about 8% less per crop. Based on this, our everyday setup now uses NVFP4.
- This does not prove there is no difference. Strata's own measurement puts NVFP4 slightly further from the 8-bit version than UD (KL 0.070 against 0.056). That gap is smaller than the run-to-run spread of these tasks; telling them apart would take dozens of runs of the same questions.
All runs in one list (including before Strata)
Table reading on the same 10 crops with the same scoring, and answers to the same questions, side by side, with the version and the PC. The earlier vision model is Qwen2.5-VL-7B-Instruct.
Table reading
| Condition | Strata | Match on 10 crops (F1) | Mean per crop | Staircase fare errors (upper + lower) | Time for those 2 |
|---|---|---|---|---|---|
| Earlier vision model (Qwen2.5-VL-7B), whole page | before | — | — | 118 + 96 | 73 s (one page) |
| gemma, strength 0 (output cap 256, as deployed) | before | — | — | both cut off, marked "unreadable" | 9 + 9 s |
| gemma, strength 0 (output cap 8192) | before | 0.72 (0.90 ignoring its flag) | 52 s | 0 + 56 | 69 + 70 s |
| Qwen, strength 0 | 0.2.4.2 | 0.86 | 106 s | 2 + 4 | 71 + 76 s |
| Qwen, strength 1 | 0.2.4.2 | — | — | 1 + 3 (1 + 16 on a rerun) | 195 + 125 s |
| Qwen, strength 3 | 0.2.4.2 | — | — | 12 + 20 | 927 + 1,060 s |
| Qwen, strength 0 | 0.2.10 | 0.85 | 86 s | 2 + 6 | 69 + 71 s |
| Qwen, strength 1 | 0.2.10 | — | — | 2 + 13 | 130 + 105 s |
| DeepSeek, strength 0 | 0.2.10 | 0.88 | 96 s | 14 + 22 | 75 + 91 s |
| DeepSeek, strength 1 | 0.2.10 | — | — | 19 + 38 | 1,160 + 1,126 s |
| Qwen, strength 0 (i7) | 0.2.10 | 0.85 | 100 s | 3 + 4 | 86 + 81 s |
| Qwen, strength 1 (i7) | 0.2.10 | — | — | 5 + 169 (a format slip; 5 + 3 once fixed) | 80 + 108 s |
| DeepSeek, strength 0 (i7) | 0.2.10 | 0.86 | 96 s | 20 + 18 | 93 + 86 s |
| DeepSeek, strength 1 (i7) | 0.2.10 | — | — | 22 + 38 | 1,224 + 1,148 s |
| Qwen, strength 0 (i7, faster split, UD) | 0.2.10 | 0.87 | 95 s | 1 + 2 | 84 + 80 s |
| Qwen, strength 1 (i7, faster split, UD) | 0.2.10 | — | — | 1 + 7 | 96 + 55 s |
| Qwen, strength 0 (i7, NVFP4) | 0.2.10 | 0.87 | 87 s | 3 + 0 | 75 + 70 s |
| Qwen, strength 1 (i7, NVFP4) | 0.2.10 | — | — | 1 + 0 | 49 + 57 s |
- Speed: on ordinary tables, gemma from before Strata was the fastest (52 s a crop); Strata's Qwen took about 2 times as long on 0.2.4.2 and about 1.7 times on 0.2.10.
- Accuracy on ordinary tables: ignoring the flag, gemma (0.90), DeepSeek (0.88) and Qwen (0.85–0.86) are about the same. In the real pipeline gemma threw its own readings away.
- Staircase fare tables: before Strata, the whole-page reader made 214 errors and gemma as deployed returned no rows. Strata's Qwen at strength 0 made 6–8, the best result. Strong thinking and DeepSeek did worse on these tables.
Answers (questions on this source)
| Condition | Strata | 13 questions besides the correspondence one: right and decisive | Left open | Mean time, 11 questions | Correspondence question (good / runs) |
|---|---|---|---|---|---|
| llm-jp (the answer model before Strata) | before | 11 | 1 (and 1 with no answer) | 39 s | 0 / 3 |
| Qwen, strength 0 | 0.2.4.2 | 13 | 0 | 35 s | 1 / 2 |
| DeepSeek, strength 0 | 0.2.4.2 | 10 | 3 | 132 s | 0 / 2 |
| Qwen, strength 0 | 0.2.9 | 13 | 0 | 24 s | 0 / 4 |
| Qwen, strength 0 | 0.2.10 | 13 | 0 | 26 s | 2 / 3 |
| DeepSeek, strength 0 | 0.2.10 | 10 | 3 | 52 s | 0 / 3 |
| llm-jp (i7) | before | 11 | 1 (and 1 wrong) | 28 s | 0 / 3 |
| Qwen, strength 0 (i7) | 0.2.10 | 13 | 0 | 19 s | 0 / 3 |
| DeepSeek, strength 0 (i7) | 0.2.10 | 11 | 2 | 46 s | 2 / 3 |
| Qwen, strength 0 (i7, faster split, UD) | 0.2.10 | 13 | 0 | 16 s | 0 / 3 |
| Qwen, strength 0 (i7, NVFP4) | 0.2.10 | 13 | 0 | 15 s | 0 / 3 |
- The answer model from before Strata (llm-jp) answered 11 of the 13 right and decisively. On the fare it gave the two amounts found in the evidence without deciding which is right. On the three-infants question its output reached the answer length limit while it was still reasoning and was cut off, so no answer came out (what it had written so far was the right reading). The mean for the 11 questions was 39 s: generation is fast, and most of the time is the search on the CPU. On the i7 PC an answer to the three-infants question did come out, but it was wrong: it treated a 5-year-old as a child fare.
- For answer scores, Strata made a small difference (11 → 13); the big difference was in table reading.
- Scores did not change with the Strata version. Qwen answered the 13 right and decisively every time; DeepSeek left the same 3 open (2 on the i7 PC). Only the interpretation-dependent correspondence question differed.
- From 0.2.4.2 to 0.2.10, Qwen became about 1.3 times and DeepSeek about 2.5 times as fast. For DeepSeek most of that comes from the change of PC, not the version alone.
Reports to Strata
Reports submitted to the official Strata project during this research: measurements in the official benchmark format, and bugs with reproduction steps and a proposed fix.
--vram-reserve-later-mib 1400
Comment · #3470What happens when the later card's VRAM fills#3702 given as a case where the engine stops
Benchmark · PR #2793RTX 3060 on an AVX-only Xeon E5-2630 v2Measurements on an AVX-only CPU, separating the effect of the PCIe slot
Issue #3407The lifeline watchdog does not stop its childIt mistakes a change of process state for another process
Issue #3409A gap in isa_guard_check's allow listtq_rows_avx512 is missing
Issue #3412ggml_tq_overlay fails with CMake 3.xIN_LIST is not available in -P mode
Comment · #3235NameError: port in strata_bench.pyReported that it happens on Linux too
Conditions and limits
- One source document. Table reading was compared on 10 tables, thinking strength on 2 fare tables, and answers on 14 questions (DeepSeek ran strength 1 on the first 3 only).
- At most three repeats. Results vary even at temperature 0, so a difference seen in one run may be noise.
- Thinking strength was compared almost only with Qwen; for other models it was checked only on DeepSeek's 3 questions.
- DeepSeek's speed is for this PC (two GPUs, 64 GB of RAM, an SSD reading 1.5–1.9 GB/s). It changes a lot on a PC with more RAM or a faster SSD. Even on the i7 PC with 125 GiB on 5 November, DeepSeek's experts did not fit in RAM, and part of them was read from the SSD.
- The reference for the fare tables was copied by hand from the printed images; the approved data itself had a few errors.
- Besides this source, the staircase rewrite was checked only on made-up tables. Tables with values to the left of the labels, or mirrored ones, are not handled yet.
- Scoring a question that depends on interpretation, like the correspondence one, against one fixed answer misjudges the models. On 4 November we changed how that one question is scored.
- The test of instructions for any document used two documents and one run per setting. The questions on the other document were already all answered right, so harder questions are needed to tell the instructions apart.
- The version comparisons in the list also differ in PC (0.2.4.2 on the earlier PC, 0.2.9 and 0.2.10 on the two-CPU PC). llm-jp was run with today's search system and index, not the exact setup from before Strata. Each question was asked once (the correspondence one three times), so a difference of 1-2 questions can come from a single run. The 5 November recheck showed that the same settings can give different answers on a different PC.